CASE STUDY · MAR 2026 → NOW
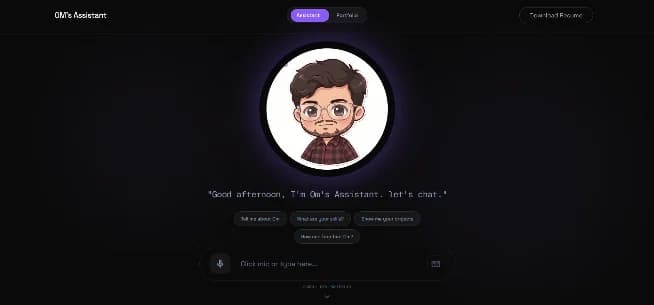
I made my portfolio answer questions in my own voice
Retrieval was the easy part. Making a ₹400/month VPS speak fast enough that it didn't feel broken — that took the actual engineering.
pauseddeploy's paused, not the project
95%LESS LATENCY ON REPEAT QUESTIONS
Semantic cache in Upstash Redis keyed on sentence-transformer embeddings. Ask something close enough to a question I've already answered and you get pre-rendered audio instead of a cold inference run.
~118msCACHED ANSWER
3CONTAINERS, ISOLATED
QdrantVECTOR STORE
1 VPSENTIRE FOOTPRINT
FIG.2 — WHAT HAPPENS WHEN YOU ASK IT SOMETHING
01fastapi
you askclean it up, embed it02redis
have I heard this?close enough → send the audio03qdrant
go find contexttop-k chunks from my notes04llm
answer, groundedno context, no claim05voxcpm
say it in my voicepre-rendered on a local GPU- api — FastAPI, request path only
- inference — isolated so crashes stay contained
- sync — pushes embeddings + audio to the VPS
DECISIONS, AND WHAT THEY COST ME
nothing here was free- I CHOSE
- cache before scaling anything
- BECAUSE
- Almost everyone asks the same six questions. Generating those answers twice was just me paying for my own laziness.
- IT COST ME
- stale answers until a re-ingest clears the keys
- I CHOSE
- generate voice on my own GPU
- BECAUSE
- TTS on a cheap VPS was the actual bottleneck. Rendering offline and syncing files kept the box small and the bill smaller.
- IT COST ME
- genuinely new questions don't get real-time speech
- I CHOSE
- split inference into its own container
- BECAUSE
- A model crash shouldn't take my portfolio down during the one hour a recruiter is looking at it.
- IT COST ME
- more compose config, more things to watch
- I CHOSE
- Qdrant instead of pgvector
- BECAUSE
- I wanted filtered hybrid search without contorting a relational schema around vectors.
- IT COST ME
- another service to run, back up, and forget to monitor